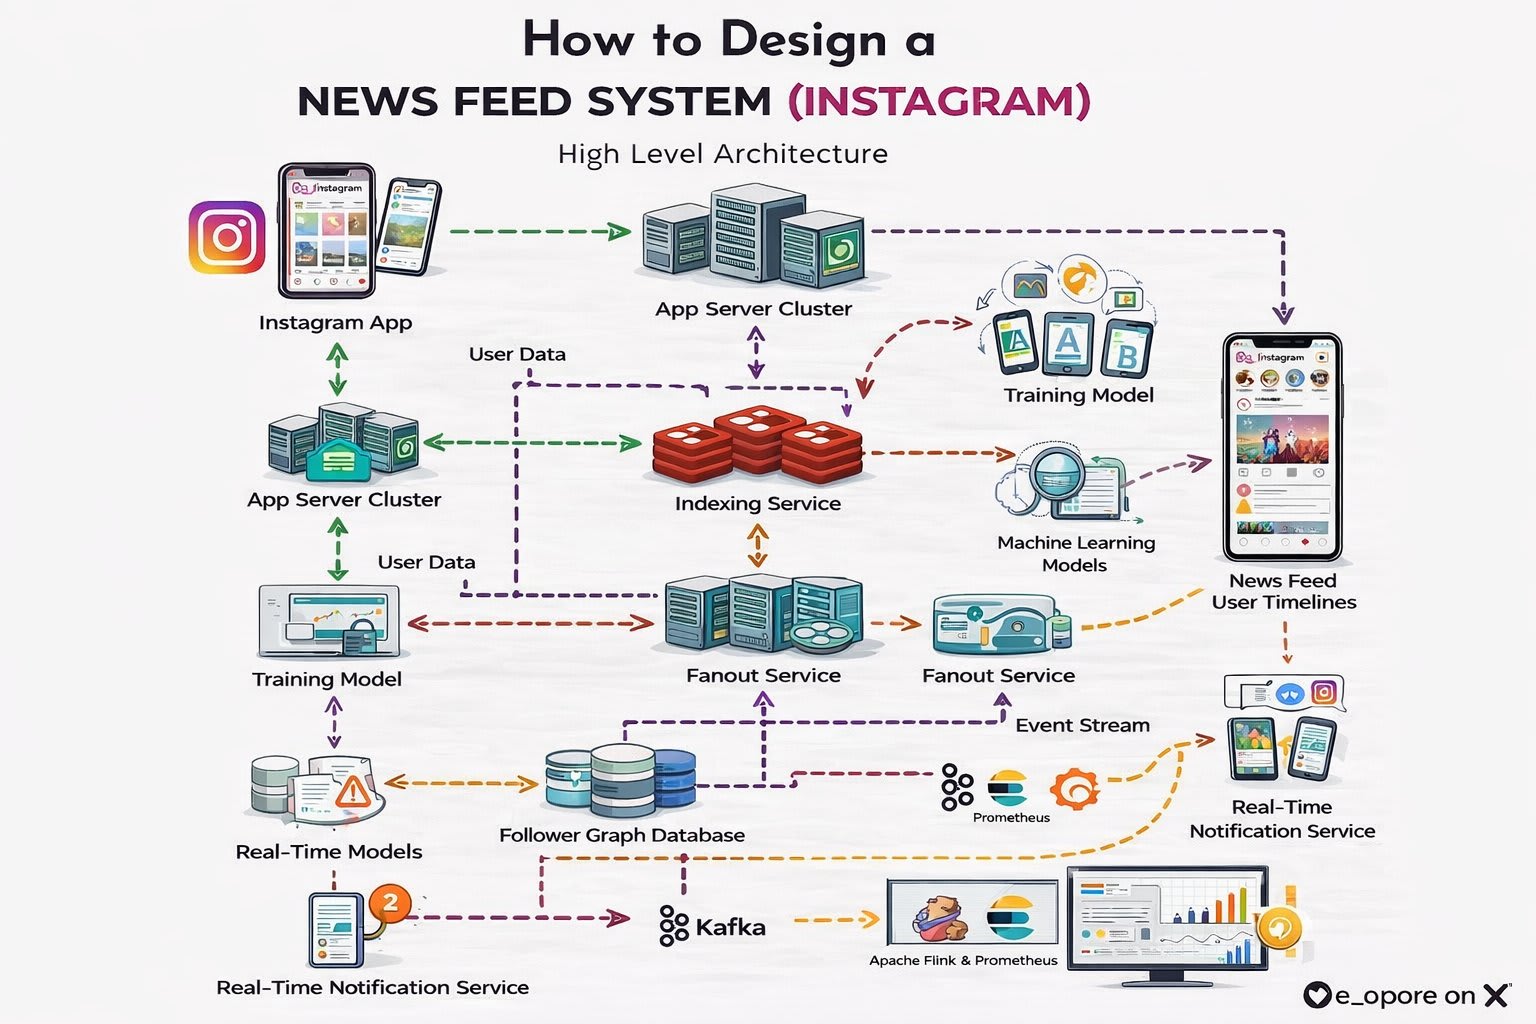
The system operates on a 𝗽𝘂𝘀𝗵-𝗽𝘂𝗹𝗹 𝗵𝘆𝗯𝗿𝗶𝗱 𝗮𝗿𝗰𝗵𝗶𝘁𝗲𝗰𝘁𝘂𝗿𝗲 that balances write amplification with read latency. When a user posts content, it is "fanned out" (pushed) to the feeds of active followers via a Feed Write Service. For users with millions of followers (celebrities), the system switches to a pull-based model where the feed is generated on-demand, avoiding the massive write overhead.
When a user opens the app, a Feed Read Service retrieves their personalized feed from a distributed cache. The feed is a pre-computed list of post IDs, ranked by the Ranking Service based on factors like recency, engagement, relationship with the author, and machine learning signals. Thumbnails and media are then fetched from a CDN for fast rendering.
The platform's core consists of 𝗵𝗶𝗴𝗵𝗹𝘆 𝗼𝗽𝘁𝗶𝗺𝗶𝘇𝗲𝗱, 𝗲𝘃𝗲𝗻𝘁-𝗱𝗿𝗶𝘃𝗲𝗻 𝘀𝗲𝗿𝘃𝗶𝗰𝗲𝘀:
- Feed Write Service: Handles fan-out of new posts to follower feed caches.
- Feed Read Service: Retrieves and paginates the ranked feed for users.
- Ranking Service: The ML-powered brain that scores and orders posts for personalization.
- Post Storage Service: Manages post metadata, captions, and comments.
- Media Service: Handles image/video upload, processing, and CDN delivery.
- Timeline Cache**: Distributed in-memory store (Redis) holding the pre-computed feed for each user.
Behind the scenes, an 𝗮𝘀𝘆𝗻𝗰𝗵𝗿𝗼𝗻𝗼𝘂𝘀 𝗲𝘃𝗲𝗻𝘁-𝘀𝘁𝗿𝗲𝗮𝗺𝗶𝗻𝗴 𝗽𝗶𝗽𝗲𝗹𝗶𝗻𝗲 powers personalization. Every view, like, and follow generates an event consumed by the Ranking Service, which continuously updates user embeddings and refines scoring models offline. Batch jobs pre-compute recommendations for cold-start users and generate the "Explore" feed.
This scale demands 𝗮𝗴𝗴𝗿𝗲𝘀𝘀𝗶𝘃𝗲 𝗰𝗮𝗰𝗵𝗶𝗻𝗴 𝗮𝗻𝗱 𝗶𝗻𝘁𝗲𝗹𝗹𝗶𝗴𝗲𝗻𝘁 𝗳𝗮𝗻𝗼𝘂𝘁 𝘀𝘁𝗿𝗮𝘁𝗲𝗴𝗶𝗲𝘀. Active users have their feed pre-computed and cached. Inactive users have their feed generated on-demand. The fan-out process is sharded by follower ID and processed asynchronously via message queues to absorb write spikes.
𝗖𝗿𝗶𝘁𝗶𝗰𝗮𝗹 𝗗𝗲𝘀𝗶𝗴𝗻 𝗣𝗿𝗶𝗻𝗰𝗶𝗽𝗹𝗲𝘀: 𝟭) 𝗛𝘆𝗯𝗿𝗶𝗱 𝗣𝘂𝘀𝗵/𝗣𝘂𝗹𝗹 𝗔𝗿𝗰𝗵𝗶𝘁𝗲𝗰𝘁𝘂𝗿𝗲 to handle celebrity users, 𝟮) 𝗠𝗟-𝗣𝗼𝘄𝗲𝗿𝗲𝗱 𝗥𝗮𝗻𝗸𝗶𝗻𝗴 for personalization, 𝟯) 𝗠𝘂𝗹𝘁𝗶-𝗧𝗶𝗲𝗿 𝗖𝗮𝗰𝗵𝗶𝗻𝗴 (feed IDs → post metadata → media), 𝟰) 𝗔𝘀𝘆𝗻𝗰𝗵𝗿𝗼𝗻𝗼𝘂𝘀 𝗙𝗮𝗻𝗼𝘂𝘁 with queue-based processing, 𝟱) 𝗘𝘃𝗲𝗻𝘁-𝗗𝗿𝗶𝘃𝗲𝗻 𝗣𝗲𝗿𝘀𝗼𝗻𝗮𝗹𝗶𝘇𝗮𝘁𝗶𝗼𝗻 for continuous model updates.
𝗧𝗲𝗰𝗵𝗻𝗶𝗰𝗮𝗹 𝗔𝗿𝗰𝗵𝗶𝘁𝗲𝗰𝘁𝘂𝗿𝗲 𝗦𝘁𝗮𝗰𝗸:
- 𝗙𝗿𝗼𝗻𝘁𝗲𝗻𝗱: React, React Native, Swift (iOS), Kotlin (Android)
- 𝗕𝗮𝗰𝗸𝗲𝗻𝗱 𝗦𝗲𝗿𝘃𝗶𝗰𝗲𝘀: Python (Django), Java, Go, Node.js
- 𝗗𝗮𝘁𝗮𝗯𝗮𝘀𝗲𝘀: PostgreSQL, Cassandra, DynamoDB
- 𝗙𝗲𝗲𝗱 𝗖𝗮𝗰𝗵𝗲: Redis, Memcached (for pre-computed timeline IDs)
- 𝗠𝗲𝗱𝗶𝗮 𝗦𝘁𝗼𝗿𝗮𝗴𝗲: AWS S3 + Global CDN (CloudFront, Akamai)
- 𝗠𝗲𝘀𝘀𝗮𝗴𝗶𝗻𝗴 & 𝗦𝘁𝗿𝗲𝗮𝗺𝘀: Apache Kafka, AWS Kinesis
- 𝗠𝗮𝗰𝗵𝗶𝗻𝗲 𝗟𝗲𝗮𝗿𝗻𝗶𝗻𝗴: PyTorch, TensorFlow (for ranking and recommendation models)
- 𝗢𝗿𝗰𝗵𝗲𝘀𝘁𝗿𝗮𝘁𝗶𝗼𝗻: Kubernetes, Docker, AWS EKS
- 𝗠𝗼𝗻𝗶𝘁𝗼𝗿𝗶𝗻𝗴: Prometheus, Grafana, ELK Stack
👉 Learn more in The Modern System Design Handbook: codewithdhanian.gumroad.com/l/ntmcf
👉 Grab the Master System Design Case Studies: codewithdhanian.gumroad.com/l/oytfng